vLLM
Translation
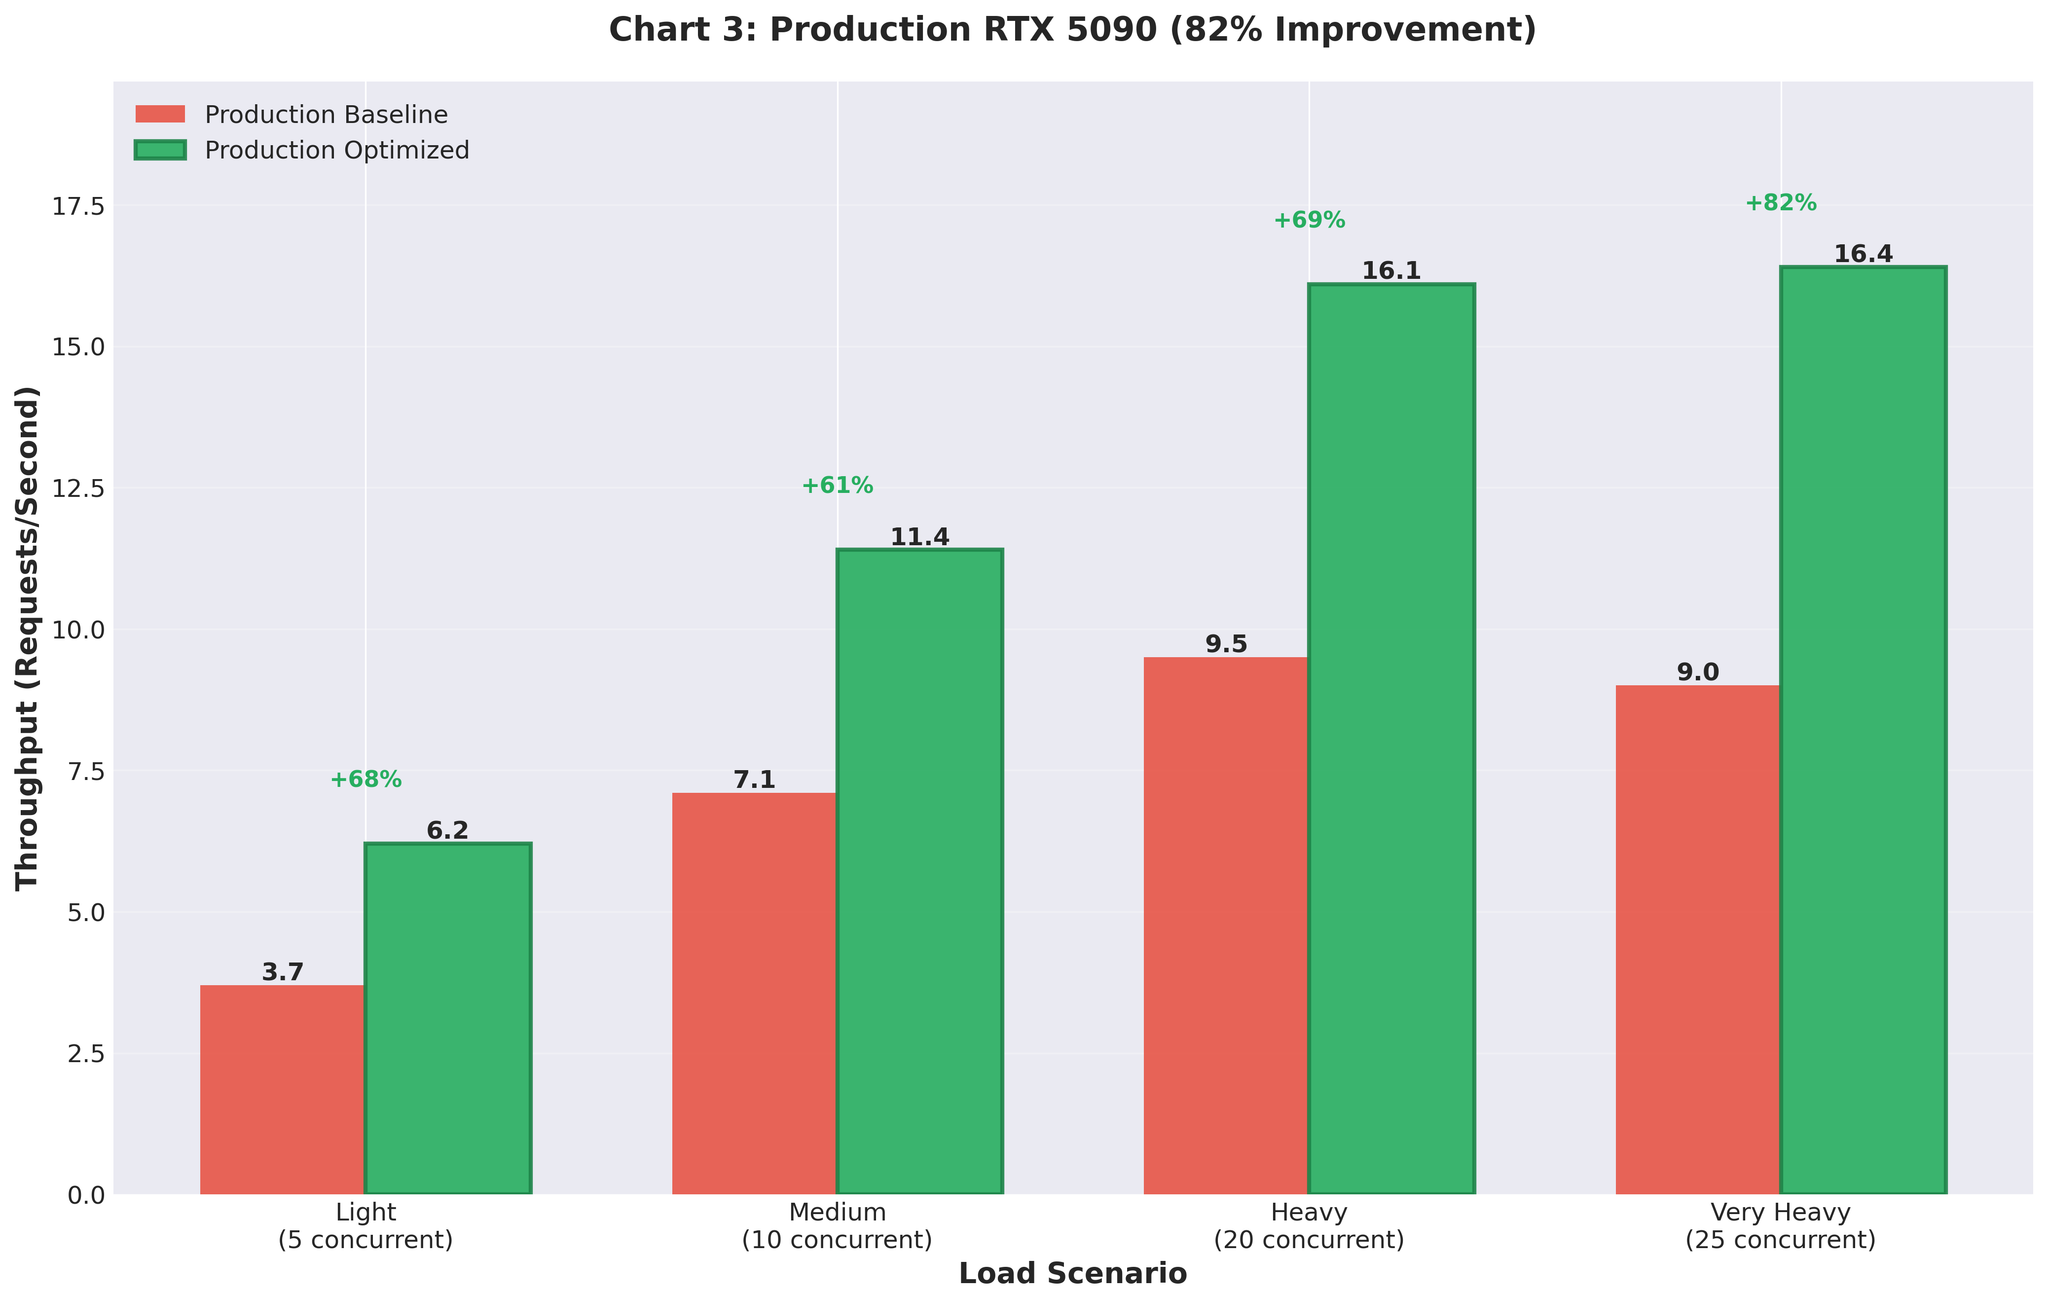
Part 2: Scaling Translation Inference: +82% Throughput
How we improved vLLM inference throughput by 82% using AsyncLLMEngine and right-sized continuous batching
Ashar Mirza - VoicePing
5 min
VoicePing benchmarks, methodology, model evaluations, and product research.
55 articles
How we improved vLLM inference throughput by 82% using AsyncLLMEngine and right-sized continuous batching

Identifying architectural bottlenecks in FastAPI + multiprocessing setup preventing efficient GPU utilization

Building a video preprocessing pipeline for facial analysis, pose estimation, and emotion detection

September 2024 - Development of an efficient async web crawler using Python, aiohttp, and BeautifulSoup for large-scale data collection

Fine-tuning Llama 3.1 for Chinese-to-English translation with hallucination mitigation strategies

Exploring RAFT methodology for bidirectional English-Chinese translation using Llama 3.1
Experience communication beyond language barriers with real-time voice translation
Get Started Free